

With dozens of LLMs (Large Language Models) available today, it’s easy to get stuck trying to choose the right one for your writing.
Plus, the decision you make impacts the quality of your content, your writing speed, and how much you spend each month.
So today, I’ll show you how I evaluate different models (paid and free) and walk you through different writing use cases, like drafting content, editing your work, brainstorming ideas, and conducting research.
Now, some people start by looking at benchmarks or leaderboards. But for me, the biggest consideration for model selection is the type of writing you’re actually doing.
Because while ChatGPT and Claude are easy ways to start, many writers need the creative nuance, voice consistency, and flexibility that a specialized model provides. Or maybe you want to run a model locally for privacy, or you need something that handles long-form content without drifting off or making things up.
But no matter what you choose, you’ll need to consider the model’s creativity, reliability, and cost.
And there’s a lot of tools to help with this.
So, let’s dive in.
The “LLM Arena” For Digital Writers
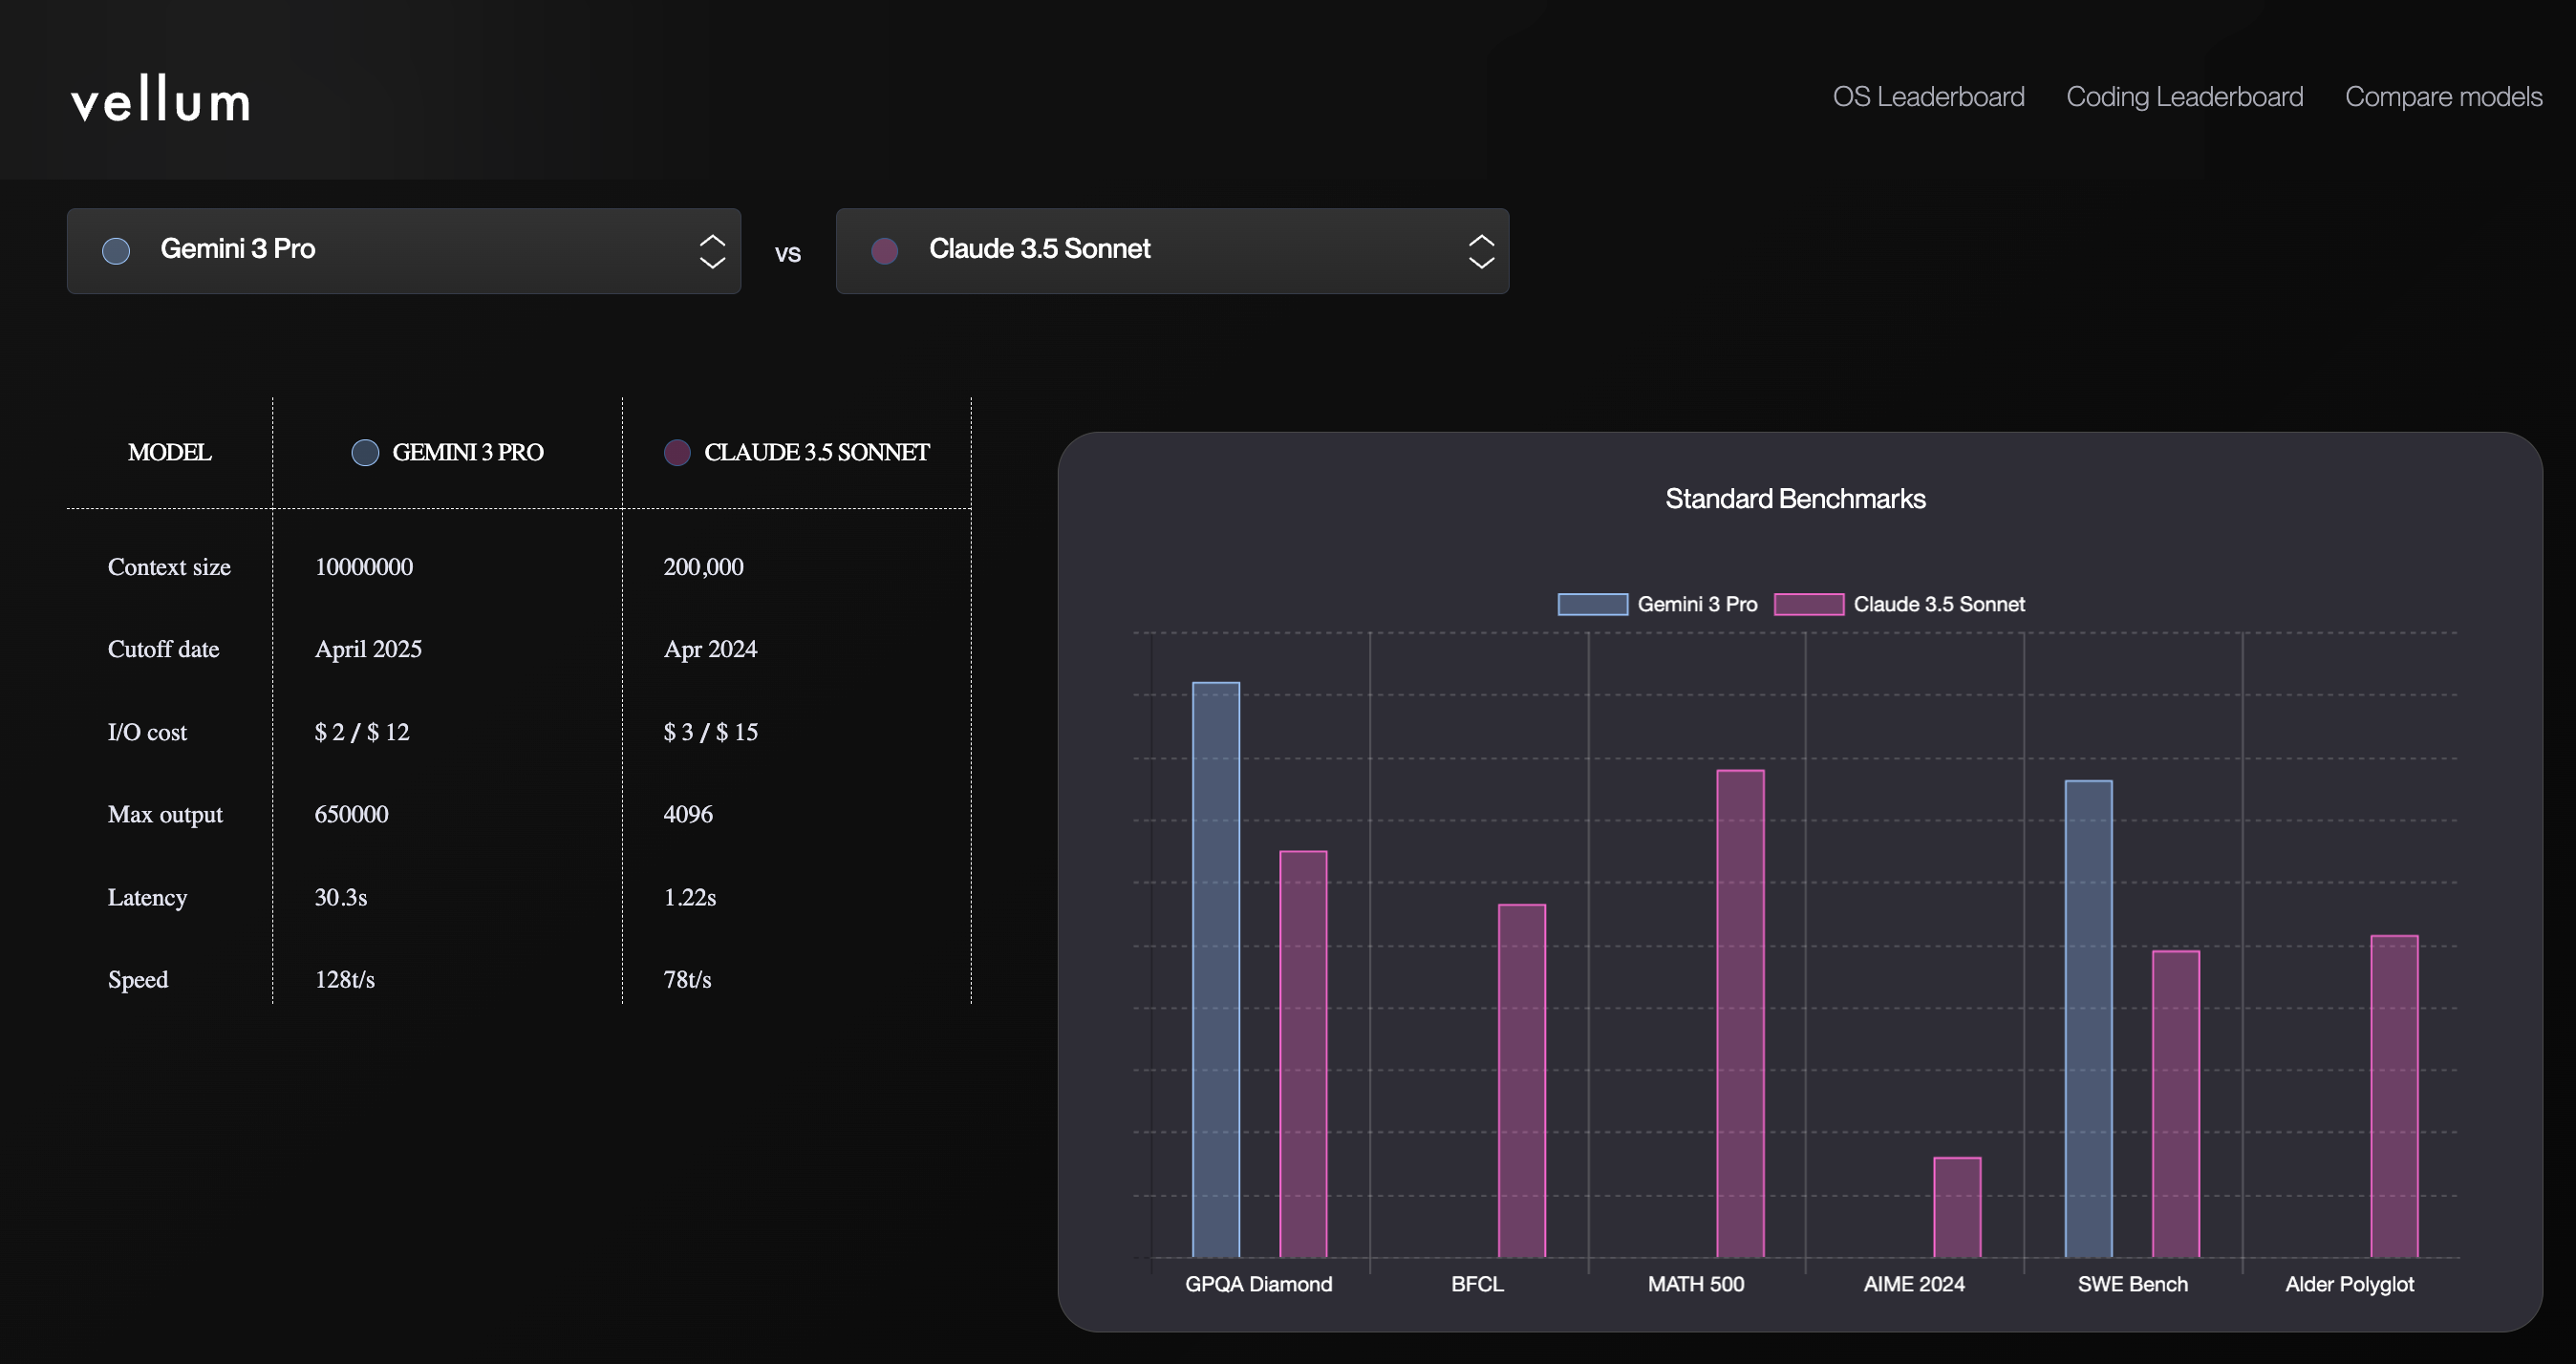
When you start researching which LLM to use for writing, you’ll quickly find dozens of leaderboards and benchmarks.
Most evaluations rank models on coding ability, math problem-solving, or general intelligence. But writers don’t need a model that can solve calculus problems. We need a model that understands voice, structure, emotional resonance, and originality.
That’s why the LMArena Creative Writing Leaderboard is a useful starting point for Digital Writers.
It’s powered by hundreds of thousands of blind user votes.
People are shown two anonymous writing samples from different models, asked to compare them side-by-side, and choose which one is better.
No one knows which model wrote what until after they vote.
This is essentially a “vibe score” for writing quality.
And it directly correlates to the things writers care about: Can this model capture different tones? Does it sound generic or distinctive? Can it maintain consistency across long pieces?
Unlike technical benchmarks that measure logic and reasoning, this leaderboard ranks models based on writing quality. Specifically, how well they perform on creative tasks like storytelling, blog posts, dialogue, and persuasive copy.
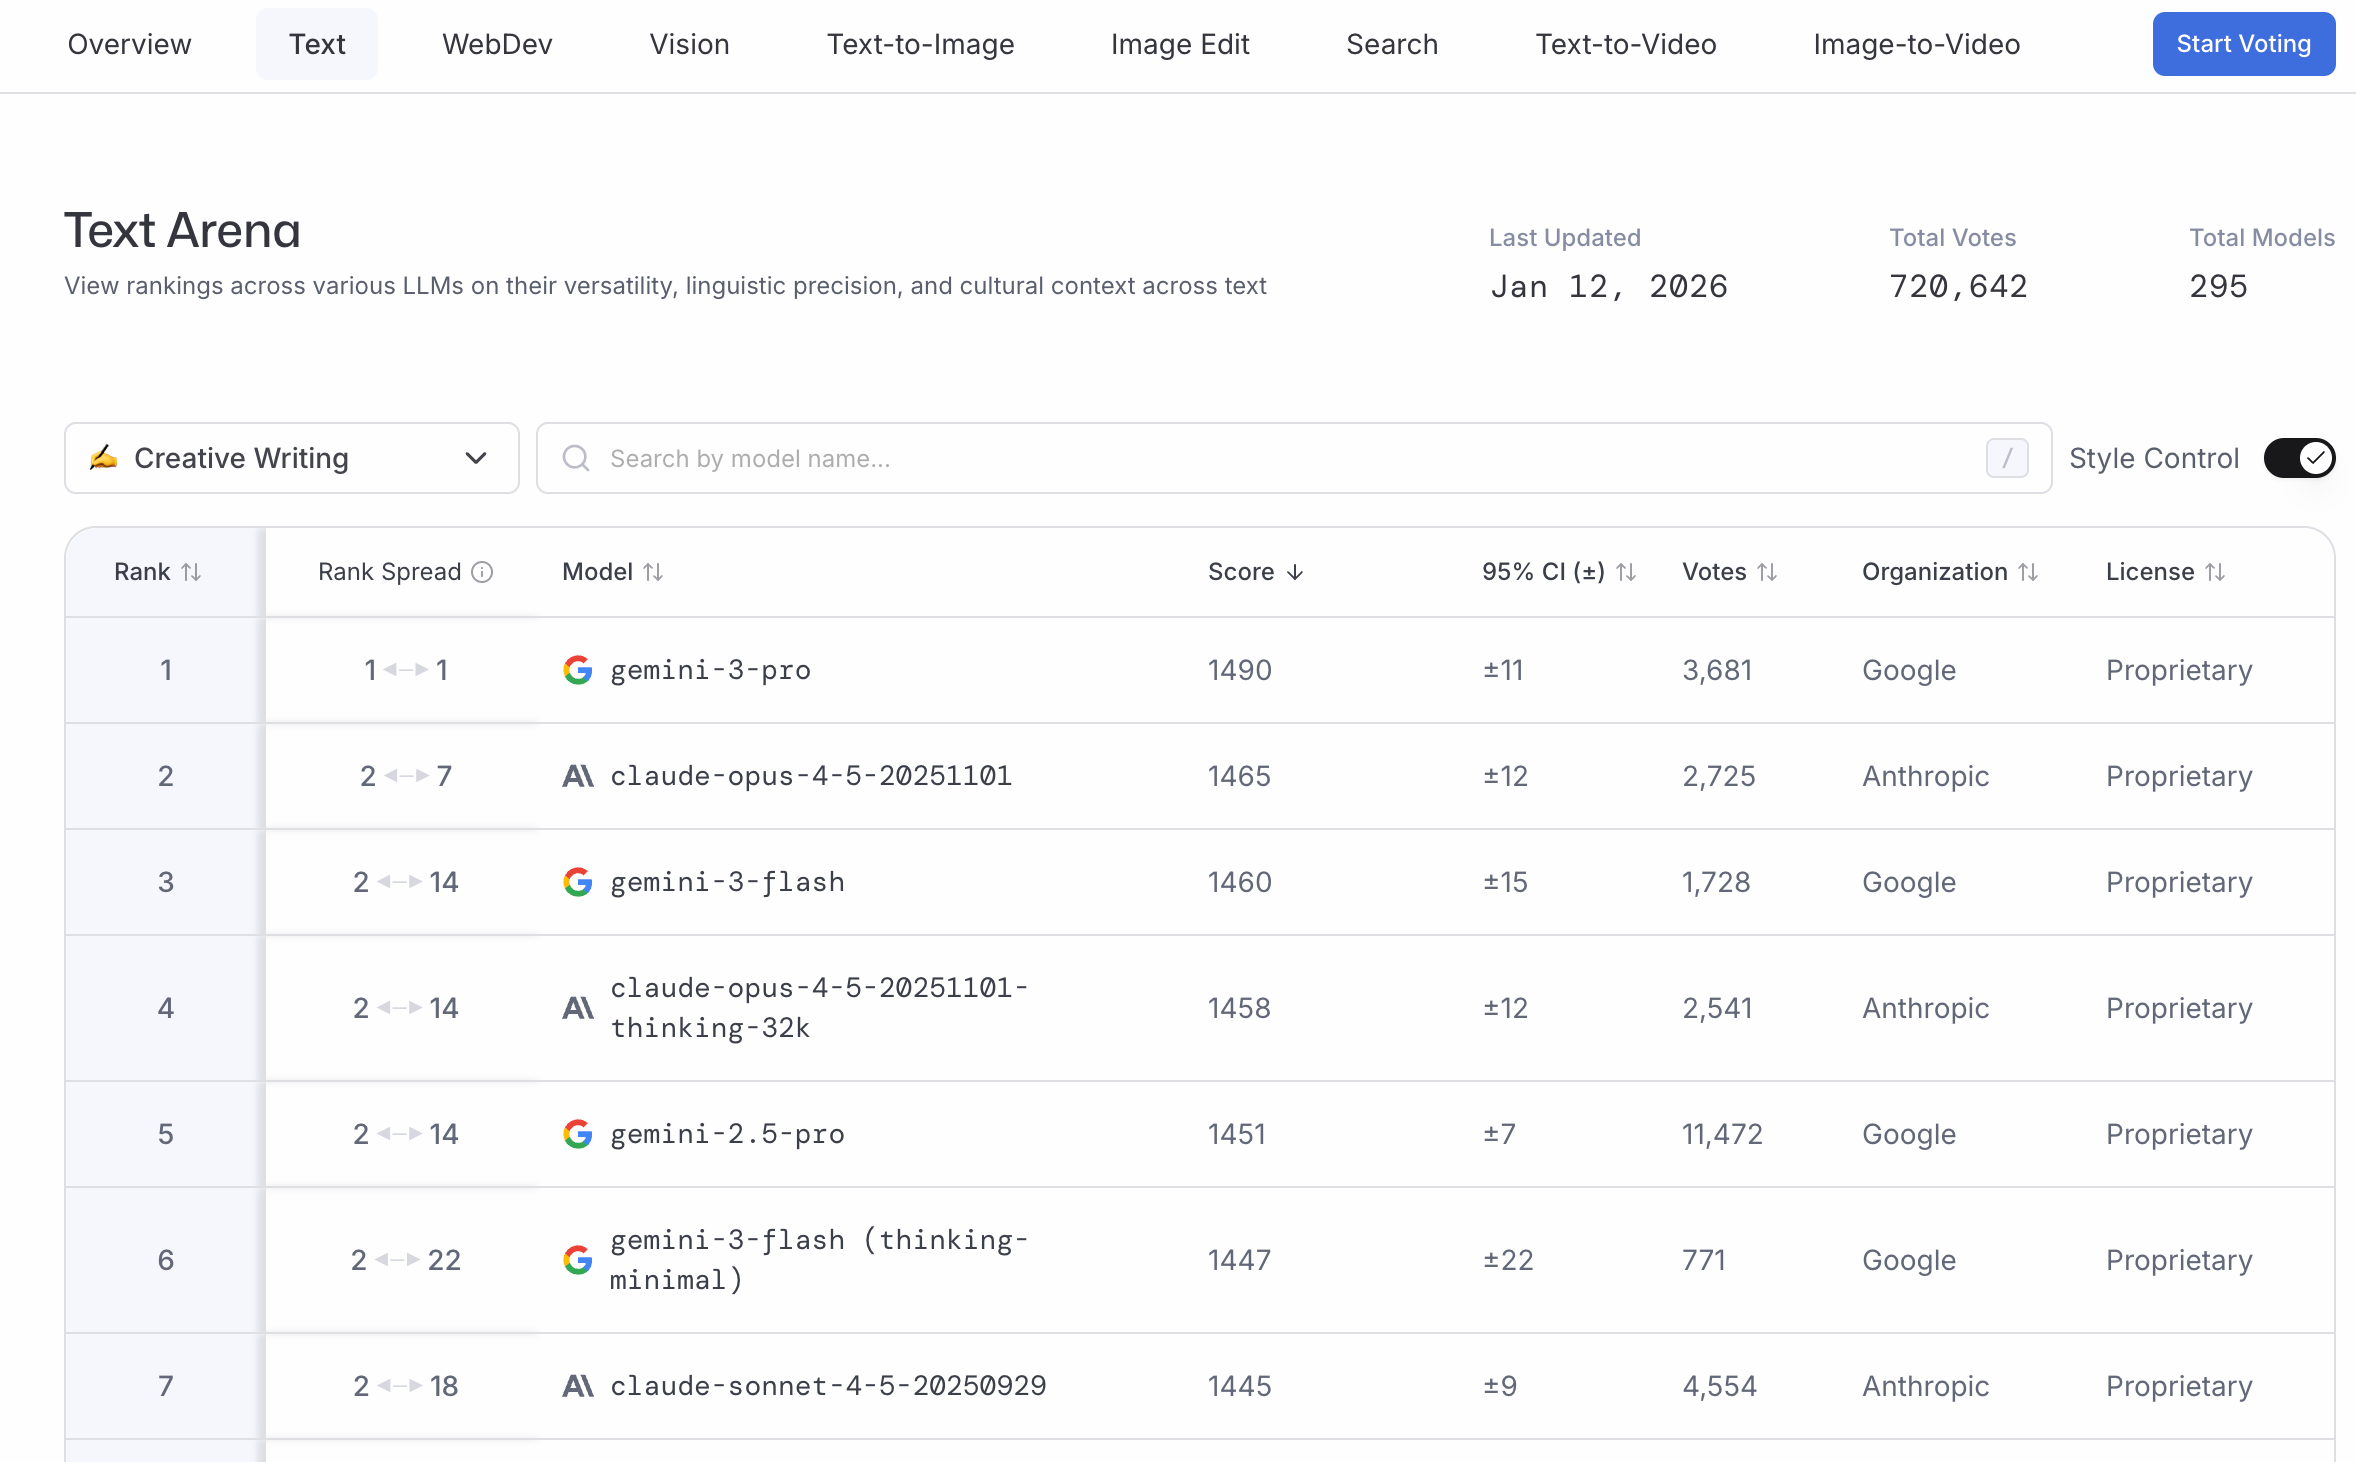
As of January 2026, Claude Opus 4.5 and Gemini 3 Pro consistently top the creative writing rankings—even when other models might score higher on math or coding benchmarks.
The models that win at technical tasks don’t always win at creative ones.
The Creative Writing Arena reveals which models the writing community prefers for content creation. And because the voting is blind, it’s harder for model makers to game the system or optimize specifically for the test.
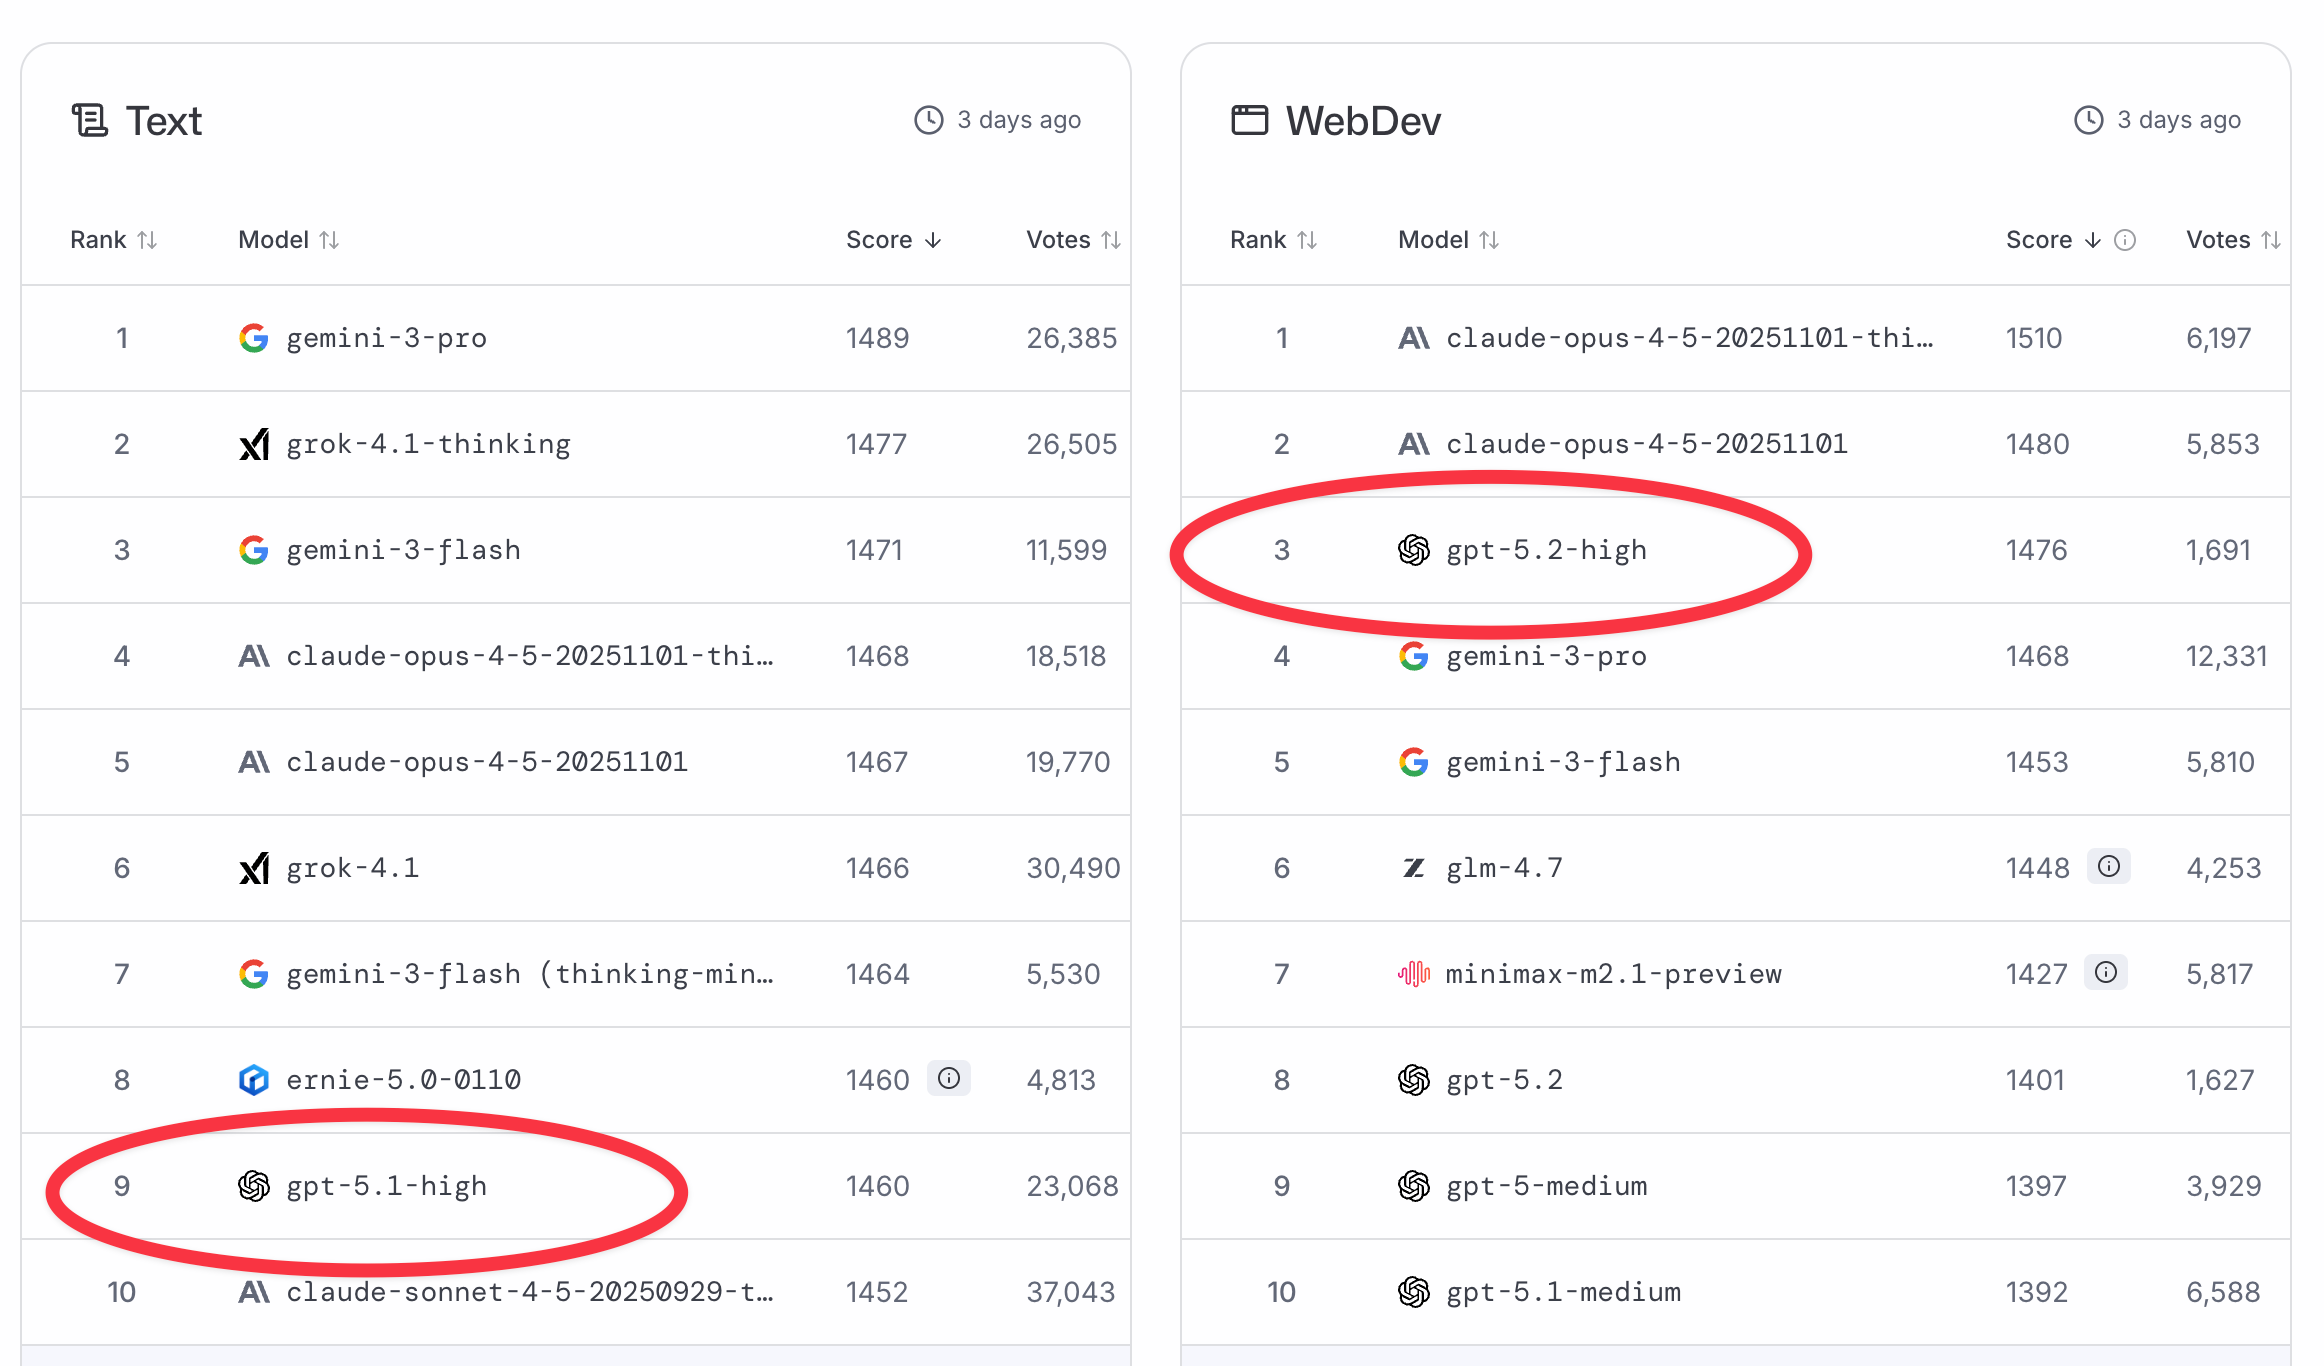
For example, a model that ranks high on WebDev but low on Text probably isn’t your best choice for a novel.
5 Key Factors To Consider When Choosing Your Digital Writing Assistant
A leaderboard rank won’t tell you which model is best for your writing style.
So, here 5 key factors you’ll want to think about:
Creativity: Some models are instruction-following machines. Perfect for SEO content, email sequences, product descriptions—anything with a template or specific requirements. Other models are creative wildcards that give you unexpected angles. These are best for fiction, brainstorming, thought leadership. In my experience, Claude and Gemini 3 lean creative. GPT-4 balances both which means it tends to be worse. The reality is most writers need different models for different tasks, but it helps to compare.
Voice Matching: Five a model three samples of your best writing, then ask it to write something new in that style. If you don’t like how it sounds after a few tweaks, move on.
Context Window: This is how much text the model remembers at once. Claude Opus 4 handles 200,000 tokens (roughly 150,000 words)—your entire manuscript, 20 previous articles to learn your style, massive research documents. Shorter windows (30,000-50,000 tokens) start “forgetting” the beginning of your document. For short-form content, doesn’t matter. For long-form projects, it makes a huge difference.
Cost Structure: Models charge per token (input and output). You can think of tokens roughly like the number of characters in your text. Claude Sonnet 4.5: charges $3/$15 per million token. It’s pretty dang cheap. 100,000 words/month costs $20-50 with mid-tier models. You really only need to worry about this if your building apps, agents, or you want to tune the model yourself. Otherwise $20 / month is the going rate for cloud access.
Open Source vs. Proprietary: Open-source models (Llama, Mistral, DeepSeek) run on your computer. Complete privacy, no monthly costs, total control. It requires technical setup and decent hardware and the quality tends to be below top proprietary models. Proprietary models (Claude, GPT, Gemini) offer instant access, consistent updates, better polish. You’re paying monthly and data lives on their servers. Most writers choose convenience. High-volume or confidential work makes open-source worth the effort.
So, how do you choose?
Well, the unsexy answer is…test them yourself.
Here’s how:
How To Pick An LLM For Your Writing (5 Tests)
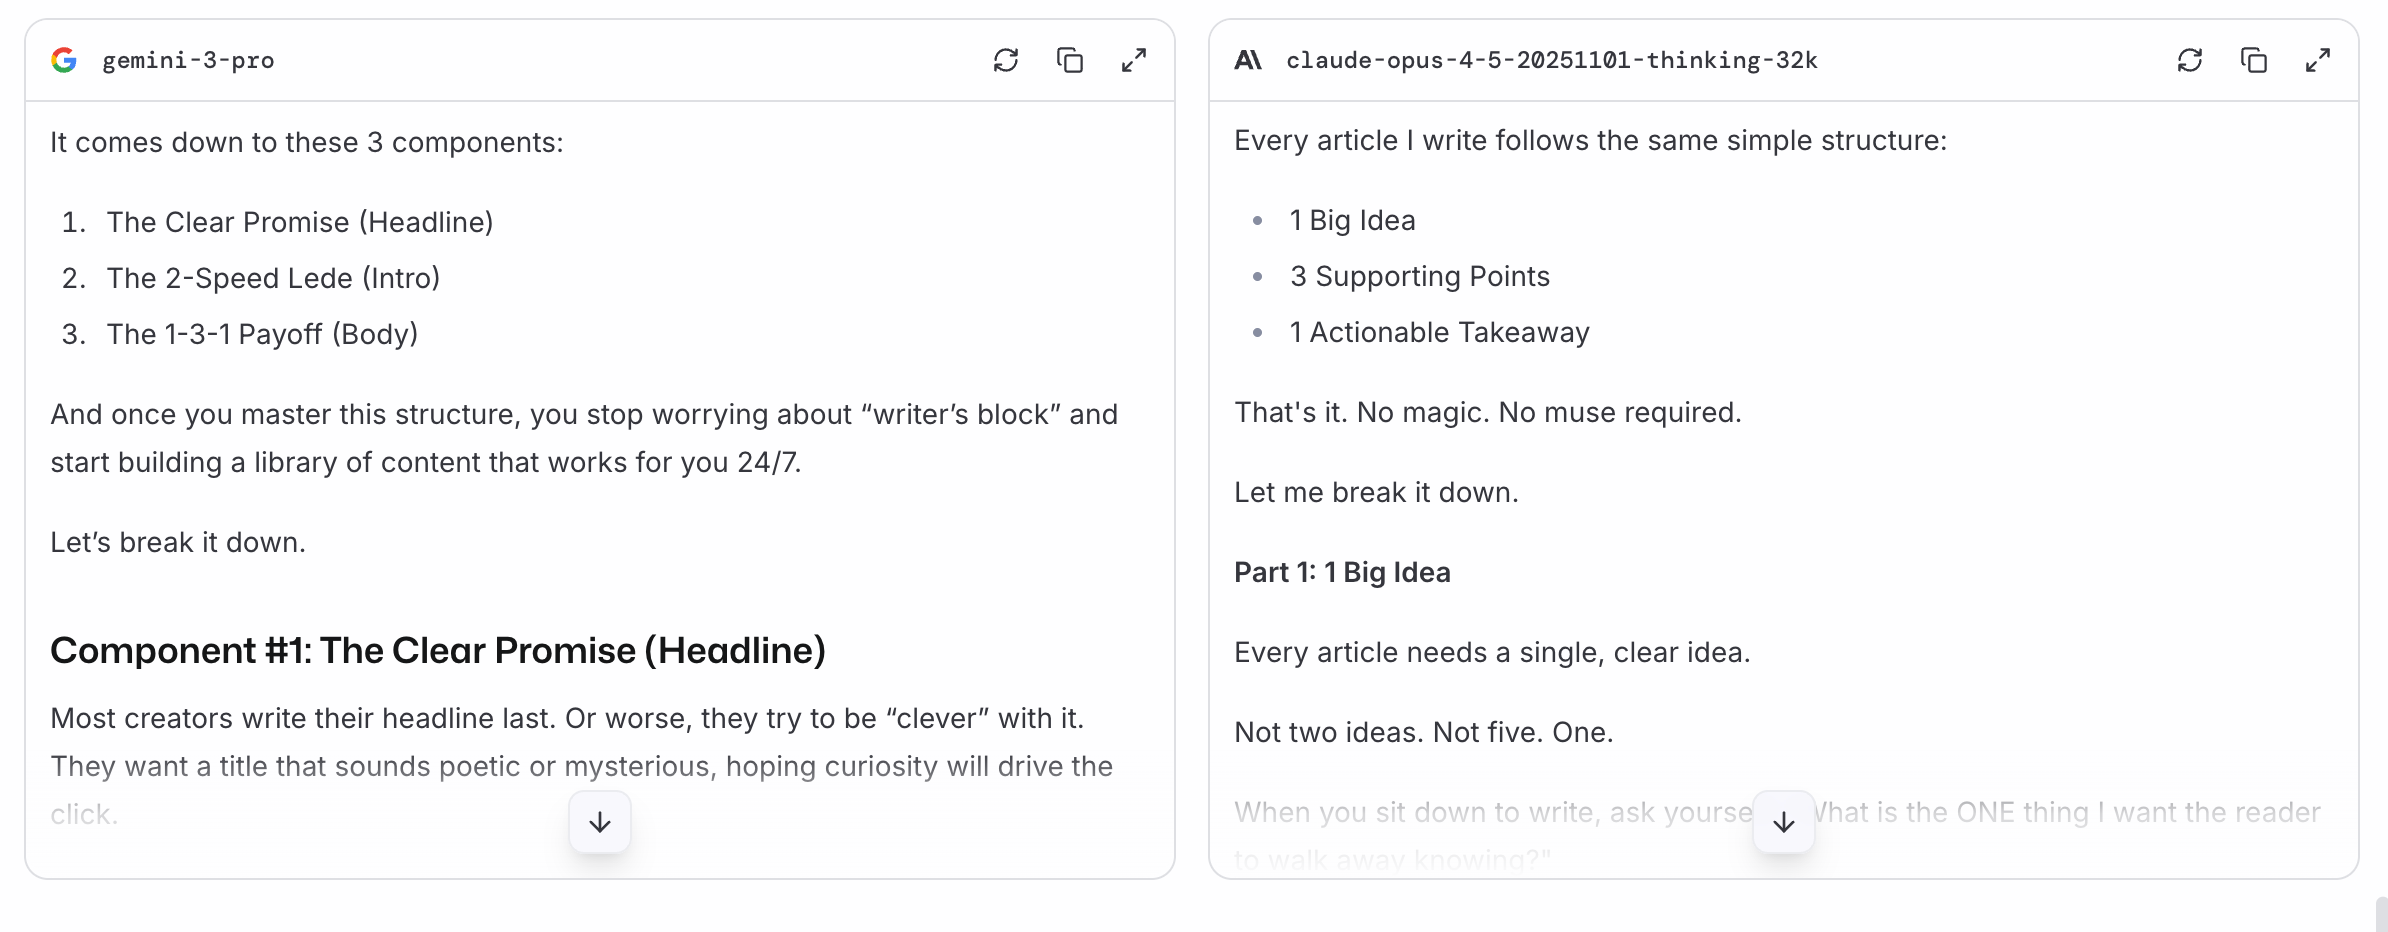
Go to lmarena.ai/new and try the blind comparison feature.
Give it a prompt:
“Write an intro for a blog post about 3 yoga tips for inflexible beginners”
“Write a product description for a banker style desk lamp for the clutter intolerant”
“Write a character sketch for Freddy, a 32-year-old millionaire tech founder has just been ousted from his company (his baby) and forced into retirement as a semi-wealthy investor.”
The arena will show you two responses from different models without telling you which is which.
Do this 5-10 times with different types of prompts and you’ll quickly develop a sense of which models match your taste. Then pick the one that sounds best to you.
Here are 5 prompts for you to test:
